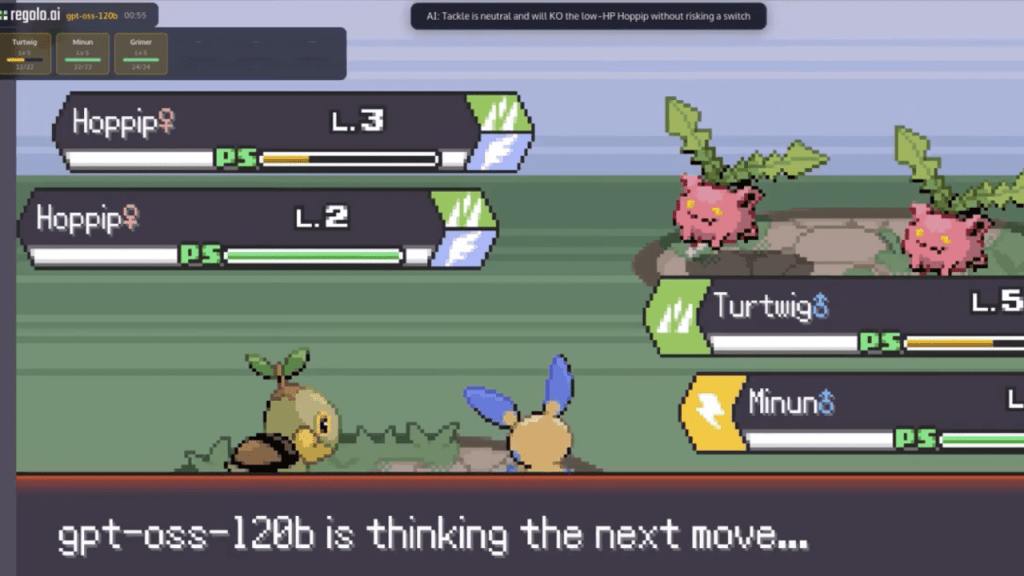
We Let an LLM Play Pokémon (roguelike) Blind — Here’s What Broke First
There's a growing cottage industry of papers showing that LLMs can play Pokémon – most test them on the original Game Boy titles —…
Stories, experiments, research and deep‑dives into the world of artificial intelligence
There's a growing cottage industry of papers showing that LLMs can play Pokémon – most test them on the original Game Boy titles —…
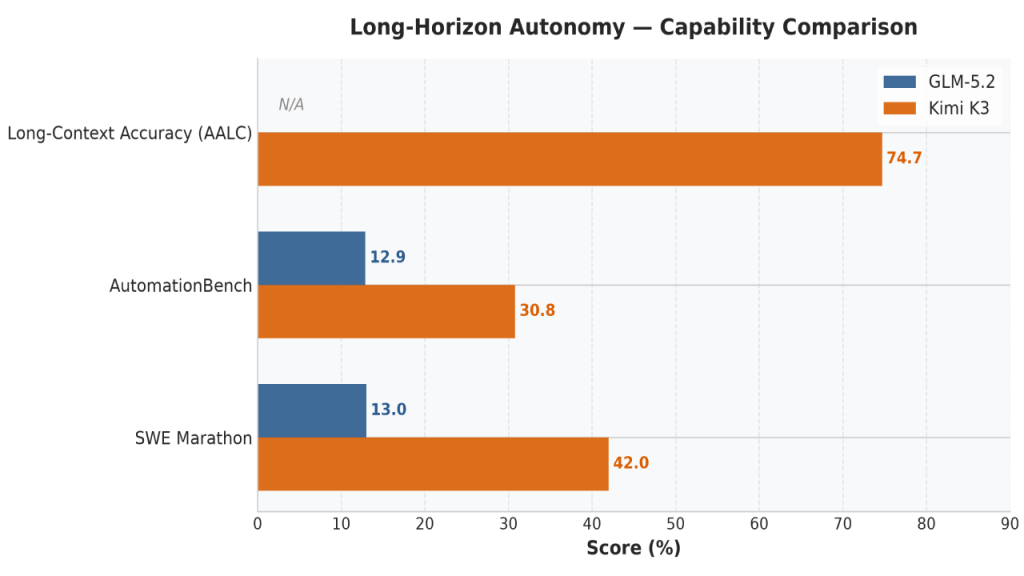
We analyzed the raw comparative benchmarks published on July 30—right after K3's weights opened—to extract a clear decision framework for engineering teams. We gather…
This tutorial shows how to build an analytics AI agent that retrieves KPI definitions with Qdrant, queries structured metrics through governed tools, and prepares…
Most LangChain tutorials default to OpenAI. This one doesn't — and it is written for a specific reader: EU-based engineering teams in regulated industries…
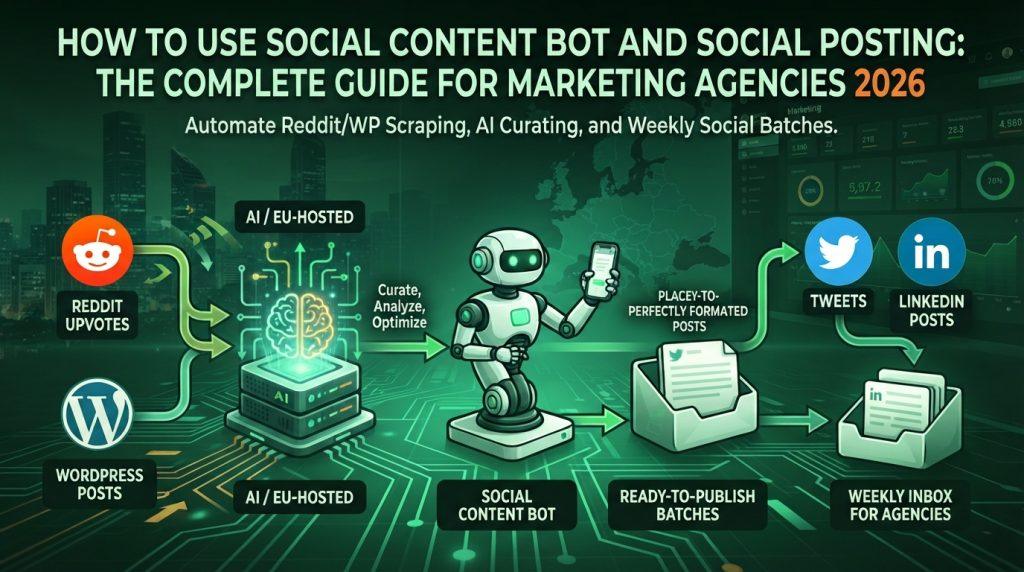
Here's how to set up an open-source bot that scrapes your Reddit upvotes and WordPress posts, feeds them through an EU-hosted AI, and drops…
TencentDB Agent Memory isn't the only memory system out there: Mem0 and OpenViking both have their strengths, but if you're building on Hermes or…
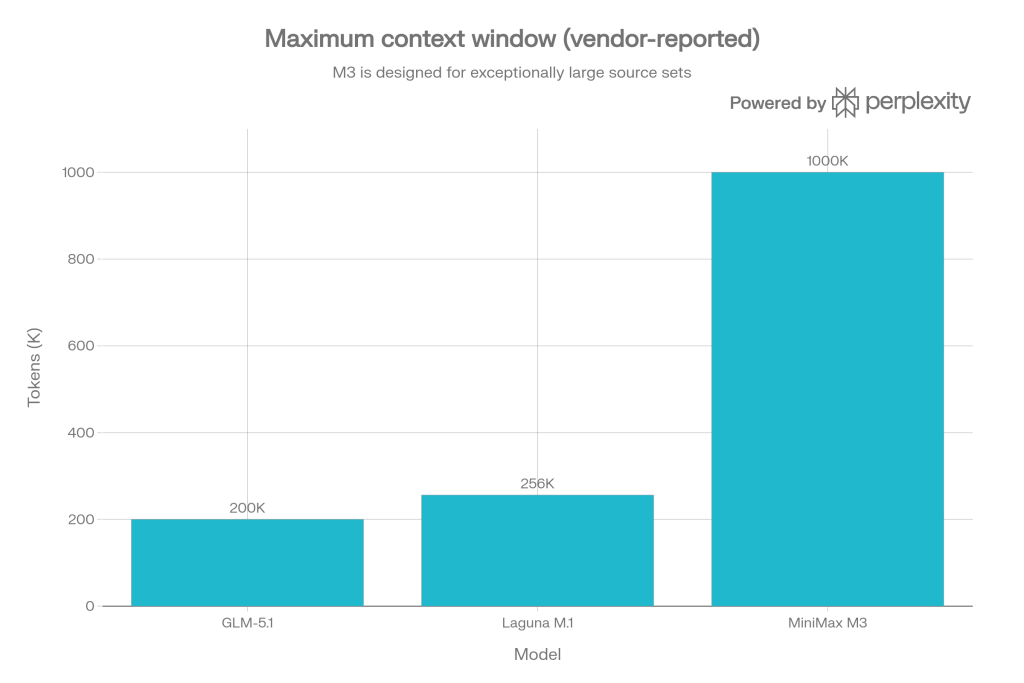
MiniMax M3 leads the published coding comparison, while GLM-5.1 is strongest for long-running text agents and Laguna M.1 offers open-weight deployment flexibility. Benchmark snapshot…
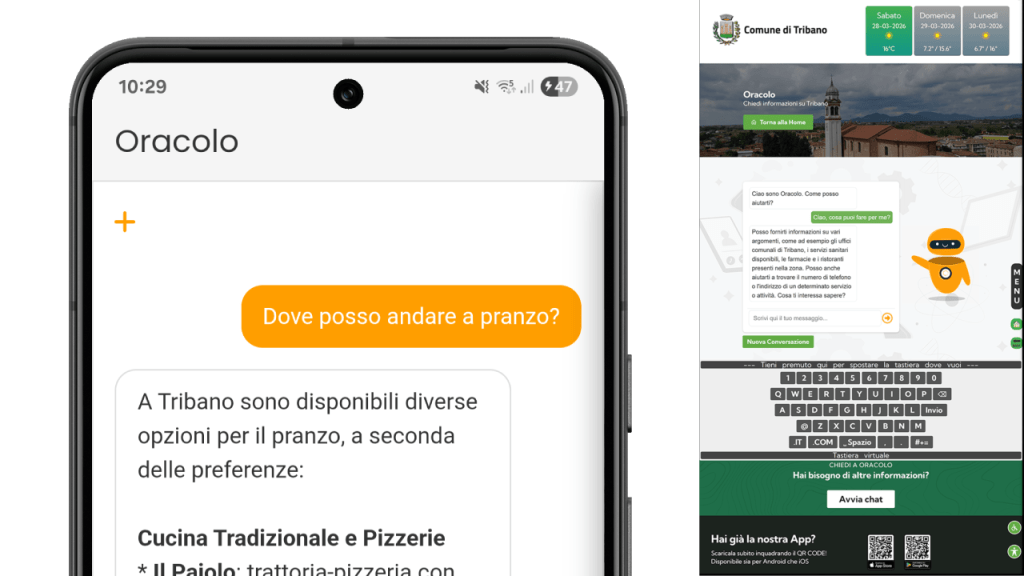
A university thesis explores the development of Oracolo, an AI assistant based on Regolo and RAG technology to improve access to public information.
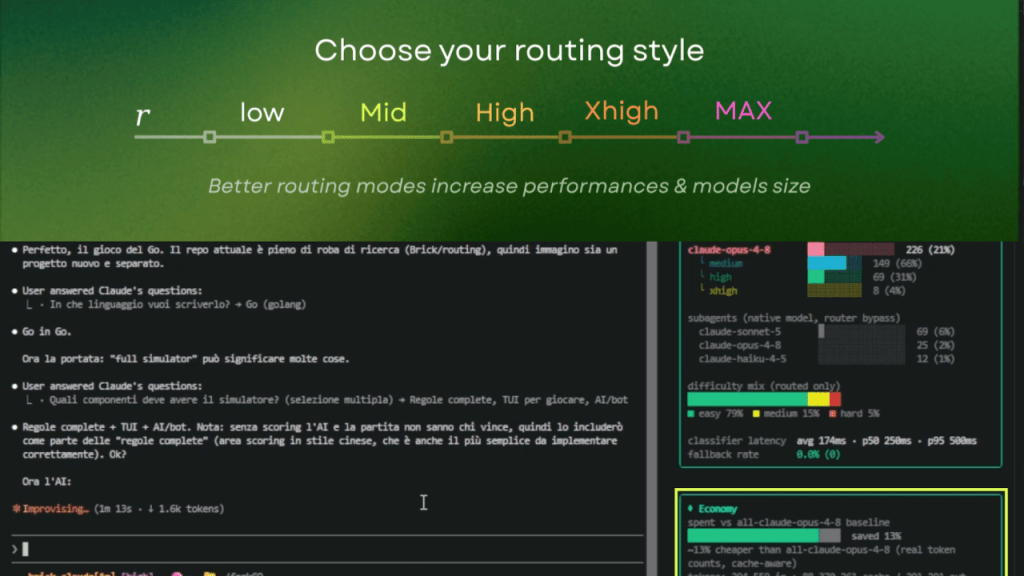
If you're running Claude Code CLI in production—or even just heavily in your daily workflow—you've probably noticed your API bills creeping up. The default…
Thinking Machines Lab has released Inkling, its first foundation model trained from scratch and designed for developers who need more control than a closed…
If you want to make a coding LLM more reliable, start by upgrading the harness instead of swapping models. LangChain’s middleware system lets you…
Announced on July 14, 2026, the model supports a 262K token context window while delivering impressive local inference performance: 163 tokens/second on an NVIDIA…